Delving into the fundamentals to see if Jev can wear the crown of "paradigm innovation."
 Core Viewpoint

 General judgment requires the simultaneous use of multiple abilities; one cannot assume it is easier than generating an answer just because it ultimately outputs a single probability.
Author: Boyang
Editor: Xu Qingyang
In the tech circle, the hype cycle is always astonishingly similar.
In September 2026, the entire Silicon Valley and open-source community were fervent about a model called Jev.
It claims to be a "System One" model, self-proclaimed to bring disruptive change.
In the past three to four years, we have become accustomed to large language models (LLMs) that, like verbose essayists, always generate hundreds of meaningless thought tokens before slowly spitting out a JSON-formatted conclusion to answer a simple "yes" or "no."
But Jev is different; it promises to give you judgments directly, provide probabilities, and do so at an astonishing speed.
Developers have gone crazy for this "fast, accurate, and ruthless" interface.
After all, when you are building a complex AI Agent, what you often need to ask is: "Is this memory relevant?" "Which tool should this request be assigned to?" "Does this incident require manual review?"
In business, everyone has spent too many tokens and delays to make a general large model generate text, explanations, and structured code for every small problem. By addressing real needs, Jev hits an extremely painful pain point.
But does it really have enough disruptive power?
When we skip the "text generation" process, how much of the judgment ability left in this black box comes from the original large language model's foundation, and how much comes from the TypeSafe team's so-called specialized training?
To answer this question, we can peel back Jev's packaging layer by layer and discuss it from several angles.
01
Predictive judgment models predate GPT
The direction represented by Jev has a very long history.
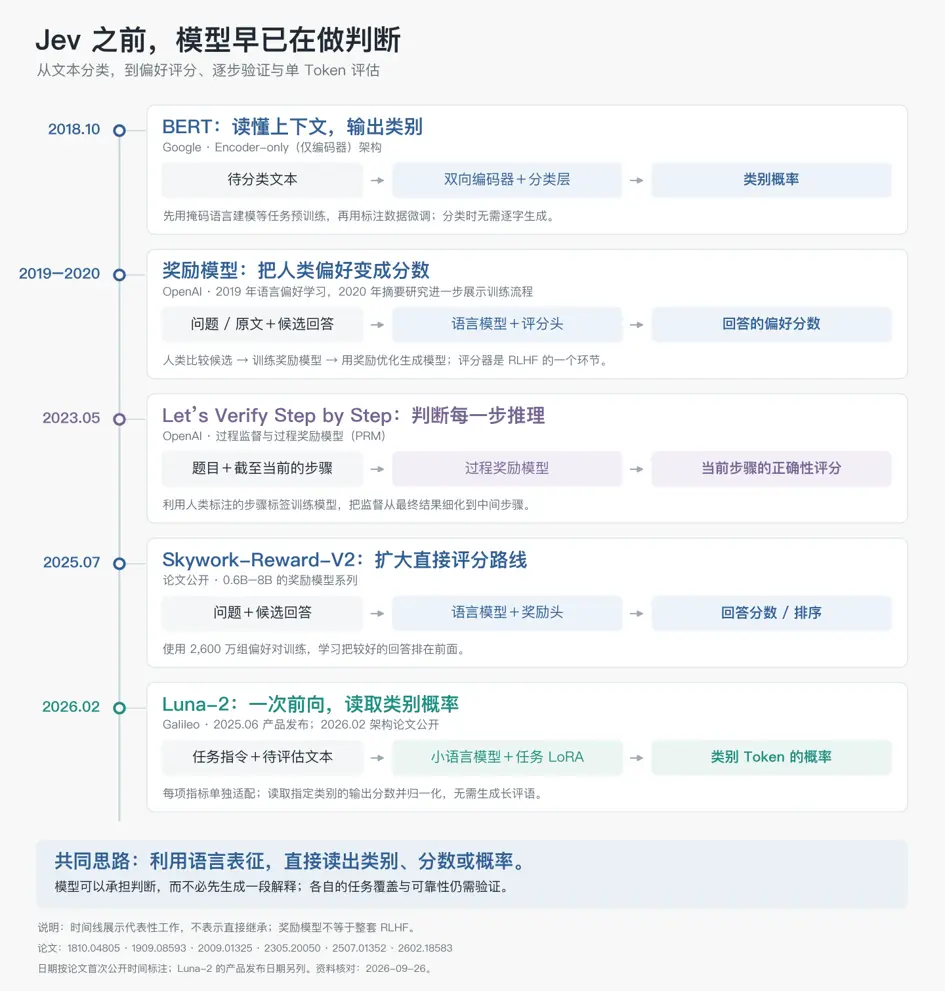
As early as 2018, Google launched BERT. Unlike the GPT-like models we are familiar with today, it adopted an Encoder-only architecture that allows for bidirectional information exchange, training the model to fill in the blanks.
Although later Decoder-only models (like ChatGPT) became mainstream for training continuation, BERT still has its advantages in clear classification tasks.
With the ability to see all information, BERT can combine various positions in the text with context to form complete feature representations, then connect to a simple classification layer, and after training with labeled emails, it can quickly make judgments.
Modern LLMs often also take on the role of classifiers.
In 2019, OpenAI began experimenting with having models learn human preferences for text in the paper "Fine-Tuning Language Models from Human Preferences."
By 2020, in research on text summarization, this technical pipeline became clearer. Human annotators first compared two summaries, then trained a reward model to learn which summary humans preferred.
In this process, human judgments were successfully transformed into a scoring function. The reward model itself does not need to write lengthy comments; it only needs to read the question and answer, then directly provide a score through the output layer of a neural network.
This is actually one of the most fundamental learning patterns for current models, which is what Jev strongly criticizes as RLHF.
Thus, "inheriting the understanding ability of language models without generating text" is not a unique genius idea of Jev.
By 2023, the well-known paper "Let's Verify Step by Step" further refined this supervision to every step of the model. Reward models, validators, and evaluation metrics developed from different tasks gradually formed several indispensable judgment tools in the AI industry.
By 2025 to 2026, related research was still advancing. In 2025, Galileo released Luna-2 and demonstrated in subsequent papers how to train small language models into "single-token classifiers," directly reading the probability of target categories through a single forward computation. Meanwhile, Skywork-Reward-V2 launched a series of reward models ranging from 0.6B to 8B, optimizing the direct scoring route for LLMs.
From the perspective of algorithm implementation, this is not inherently difficult. Making simple changes to LLMs to calculate candidate scores directly from internal hidden representations, rather than spitting out a bunch of words, has many methods.
In the subsequent replication experiments, we can see more than three.
So what exactly has Jev brought that is different in this wave?
From the current architecture decryption and official explanations, Jev's core differentiation is reflected in two dimensions.
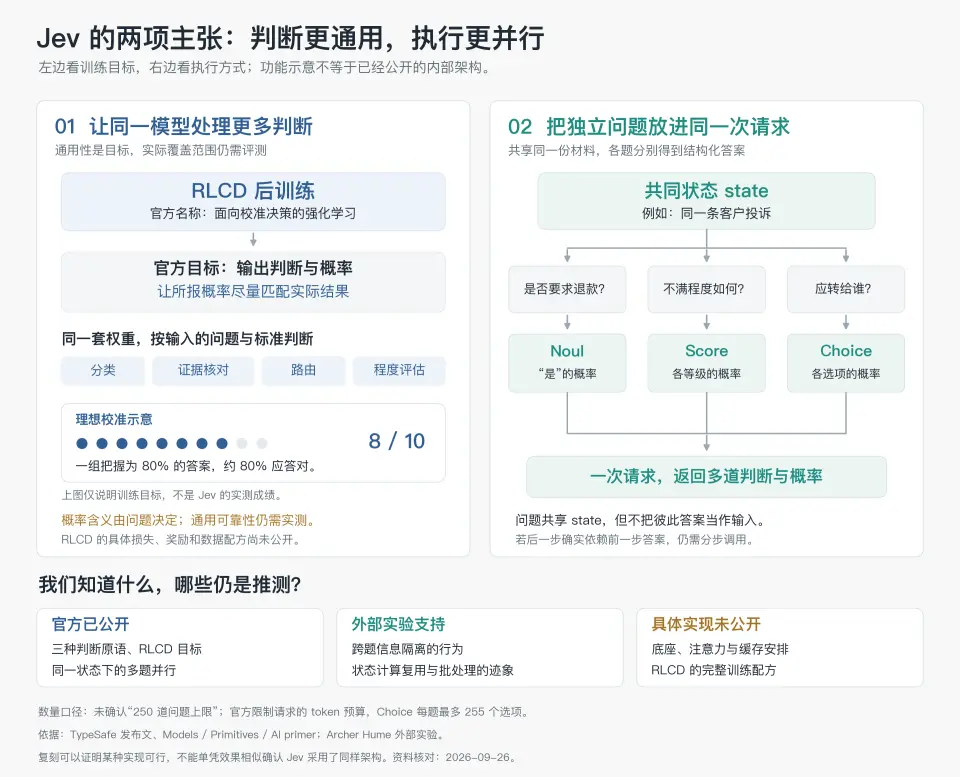
First, it is a more general change, thanks to its brand-new post-training method.
Past scorers were mostly trained for single tasks. Jev is no longer limited to a specific scoring type but attempts to provide an extremely general probability interface.
Moreover, this generality refers to factual probabilities rather than human preferences.
This time, the TypeSafe team placed "probability calibration" at the absolute center of the training objective, calling this method RLCD (Reinforcement Learning for Calibrated Decisions). Traditional preference reward models (RLHF) seek the probability of human preferences rather than the probabilities of real-world events.
Second, it is the extreme exploitation of parallel computing in architecture.
Jev changed the way information flows through the model. Past scoring models had little modification for parallel answering because the main goal was to train dense reward models, scoring each token that came out.
But this time, Jev can answer up to 250 questions on the same material. As long as there are no dependencies between the questions, they can be executed in large-scale parallel batches.
How is this achieved?
Although Jev itself has not disclosed its architecture, based on its actual performance and numerous attempts to replicate Jev, we can roughly outline its contours.
02
Piecing together Jev's original appearance from testing and replication
Let's first look at what TypeSafe has currently disclosed.
Outside the black box, TypeSafe has clearly published the interface. You can provide two things to this interface:
State: Equivalent to the original text of a long reading comprehension (e.g., a long customer complaint record or system log).
Questions: For this original text, you can simultaneously pose several questions. The questions do not interfere with each other. After the system receives these independent answers, it is up to the coder (you) to decide how to proceed with the next business logic.
To standardize the questions, TypeSafe has narrowed the questioning methods down to three primitives:
Noul (Yes/No questions): Ask "whether," directly returning a probability between 0 and 1 (e.g., Is this urgent? Returns 0.95).
Choice (Multiple-choice questions): Ask "which one," providing several options and returning their respective probability distributions (e.g., Forward to the tech department 0.8, forward to the finance department 0.2).
Score (Scoring questions): Ask "to what extent," returning the probabilities of various levels and the final weighted score (e.g., Customer anger index 4.5).
If the goal is to have the program make common judgments, these three primitives cover a large portion of output forms, and almost all judgments can be transformed into these three types of questions.
Finally, the program receives the numbers and takes action according to its own rules.
The official promise is that Jev will only read the State once. Subsequently, all questions will make parallel and independent judgments on this state in the same request.
Independence means that multiple questions cannot reference each other's answers. If your second question must rely on the result of the first question, you can only send requests in two batches.
Therefore, TypeSafe encourages a usage called "Speculative fan-out": for example, when handling a customer complaint, even if it turns out this is not a system fault, the program can initially ask "Is it a fault?", "How serious is the fault?", "Who should it be forwarded to?" Once the system calculates all answers in parallel, the downstream code logic can discard the useless results.
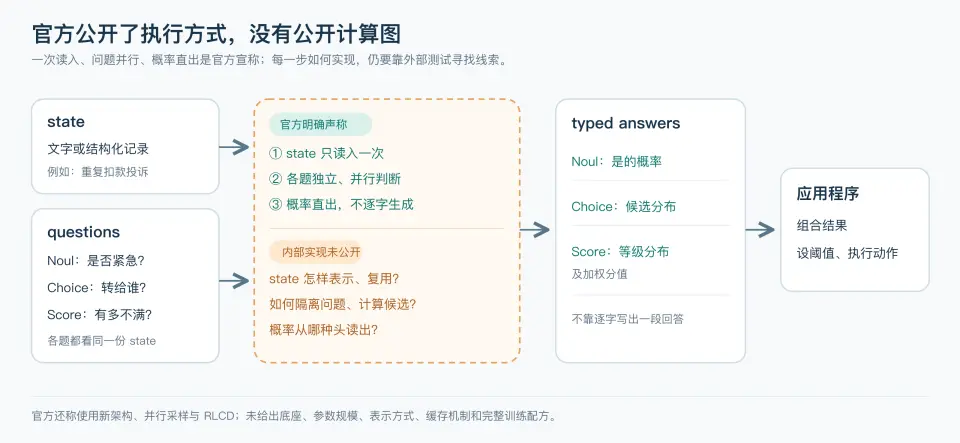
Currently, this is all the main information we know that has been officially disclosed.
After Jev gained attention, Archer Hume conducted a series of black-box tests, from which we gained many insights into how Jev processes state text. At the same time, open-source replication projects like Kev, NanoJev, and minojav have sprung up like mushrooms.
By comparing which replication projects' test feedback is closer to the real Jev, we can reverse hypothesize their true internal architecture.
While we cannot say these replications 100% restore Jev's essence, they leave huge black holes between the official interface documents, such as how the original text shares the state? How are ordinary candidate options formed into feature representations? At which step do they influence each other?
Through this lens, we can glimpse a rough outline.
Next, we will use a specific request to retrace the "internal digestion" process of this black box large model.
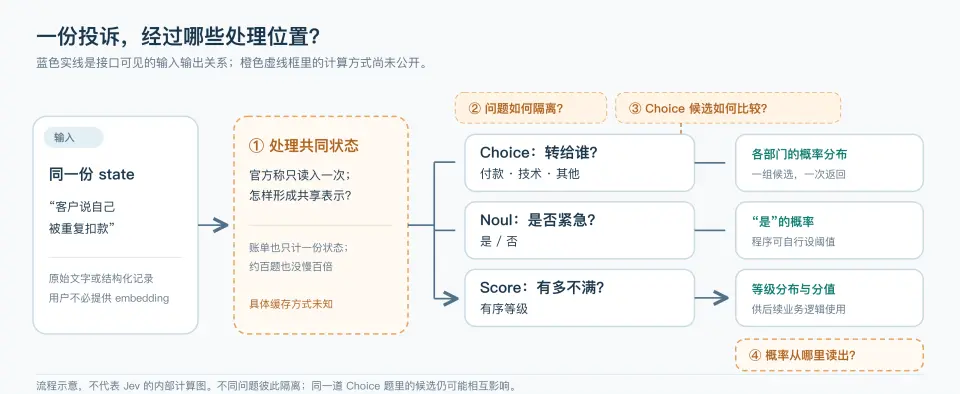
First, we need to clarify the information structure that Jev actually processes. A complete handling includes three parts: the State (e.g., that long complaint text) as shared background, several independently posed Questions, and the corresponding Options for each of these questions.
First stop: processing common information
If each question has to read through tens of thousands of words of complaints from start to finish, the more questions there are, the more redundant computational power is wasted.
So the best method is that all questions can just read the question once and then use it.
To verify whether Jev really achieved "reading only once," researcher Archer Hume reviewed the API's billing statements and latency data: when submitting the simplest yes/no question, the billing showed 268 input tokens; when increasing to two questions, it became 276. The additional cost was merely the word count of the new question itself, and the system did not repeatedly bill for the common State material.
At the same time, before the number of questions increased to nearly a hundred, the server's response time was almost a flat line.
Although the commercial billing rules and batch processing masked the true computational records of the graphics cards, this phenomenon closely aligns with the official statement of "shared materials read only once, batch calculation for each question."
For this information architecture, the restoration of the open-source project Kev is currently the clearest.
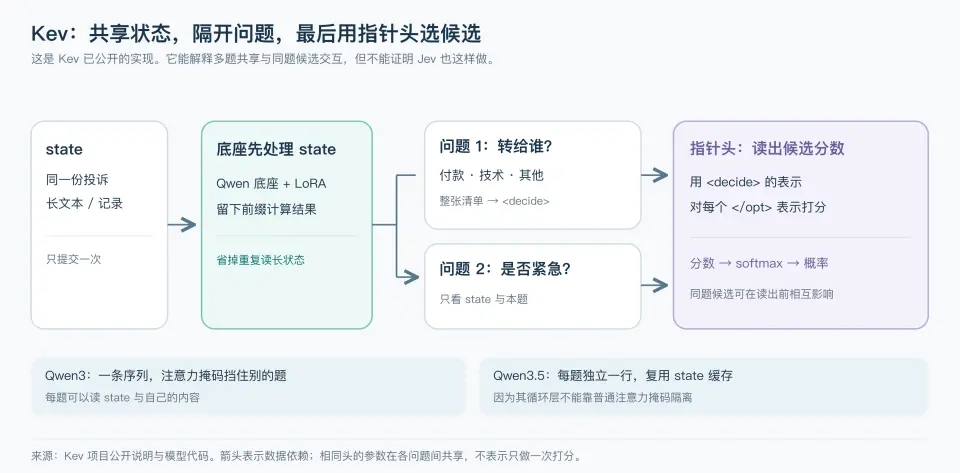
Kev first processes the status all at once, freezing the intermediate results calculated in the Kv Cache. Next, these 50 questions share this Kv Cache for further calculations, eliminating the need to read each question individually.
Second stop: Question Splitting
But another key question is, are these batch-calculated questions really isolated from each other as the official claims?
Archer Hume designed a clever "code experiment" for this purpose. He inserted the phrase "the code is ZEBRA-7741" into question A, and then in the options for question B, he had the model select "the code mentioned in another question." The results showed that Jev's probability of giving the correct code was 0.00. However, if this code was removed from question A and placed into the shared State text, the probability of question B giving the correct answer instantly soared to over 0.90.
This constitutes strong evidence that there is strict physical isolation between the questions: shared materials are visible to all questions, but adjacent questions absolutely cannot "sneak a peek" at each other.
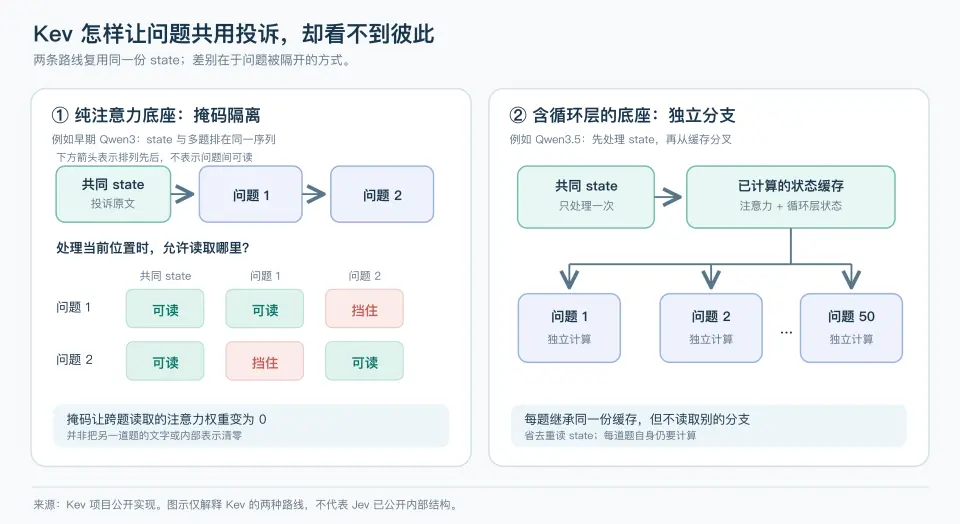
To ensure the questions could be separated, Kev used two methods.
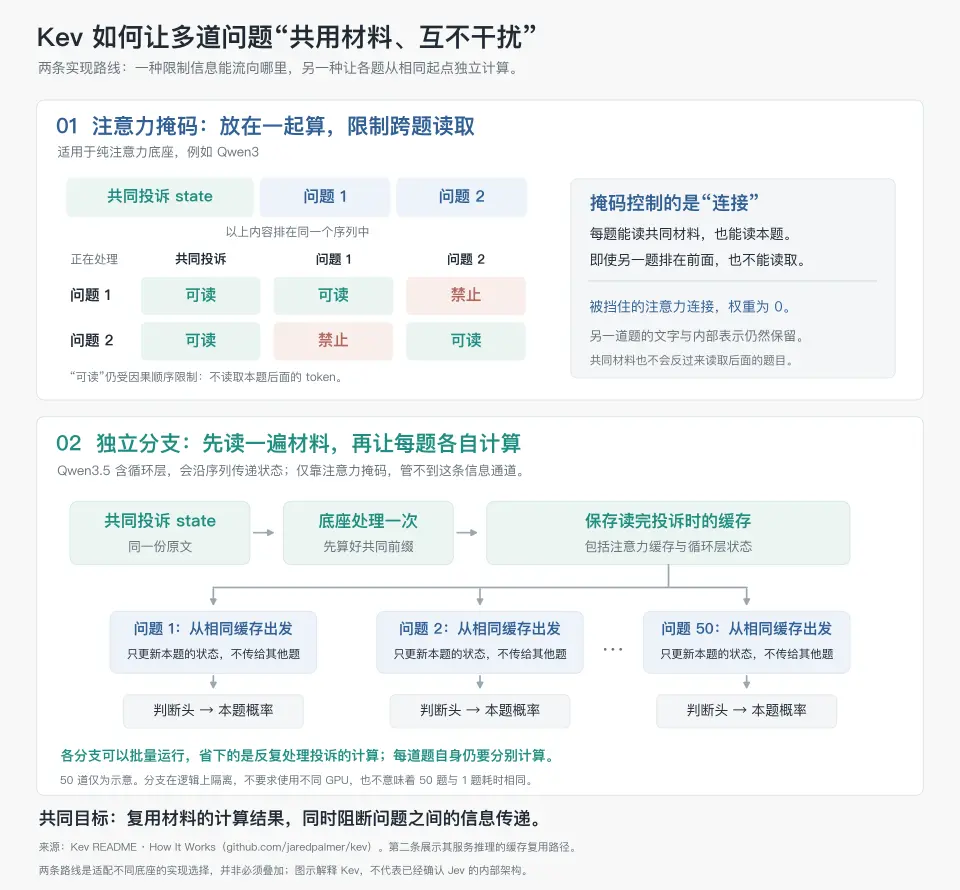
The first method is the attention mask. With it, when the system calculates [frozen original complaint] + [question 1] + [question 2] together, as long as the model is processing question 1, the mask mechanism will forcibly turn the area for question 2 into a state with a value of 0, forcing it to "pay attention" only to the shared original complaint and itself while answering.
The second method is independent branch reuse. When using bases with cyclical features or specific architectures (such as Qwen3.5 mentioned in the text), the attention mask cannot be separated. Therefore, when using these models, once the model reads the original complaint, it will start from this frozen memory and directly split into 50 parallel highways (independent branches).
Since each branch perfectly inherits the already processed complaint memory from the main road, they also enjoy the benefit of not having to re-read the original text.
Third stop: Calculating Options
Now that the state is shared and the questions have been split, how does the model calculate and process those candidate options within a split multiple-choice question?
At this point, the model is presented with several candidate options, such as "Finance" and "Technology." The most traditional approach is Linear Head plus Softmax. This is the model used by Zefan Open-Jev when attempting to replicate Jev.
You can equate it entirely to an absolutely closed "black box blind review." The contestant "Finance" performs in the black box, and based on a rigid scoring guide (which is the function of the linear head), you give them an absolute score of 80, then "Technology" enters the black box, and you give them a score of 90. These two contestants never meet, and you never compare them. Finally, you use the Softmax mathematical formula, which specifically calculates percentages, to convert the absolute scores of 80 and 90 into winning probabilities.
In this hypothetical process, if we insert a completely illogical distraction into the option pool, such as "bad weather," it would at most serve as cannon fodder in the denominator, slightly shrinking the percentages that everyone receives. However, since the scores of 80 for Finance and 90 for Technology are already written in pen on paper, their "relative odds" can absolutely not be shaken by the addition of a distraction.
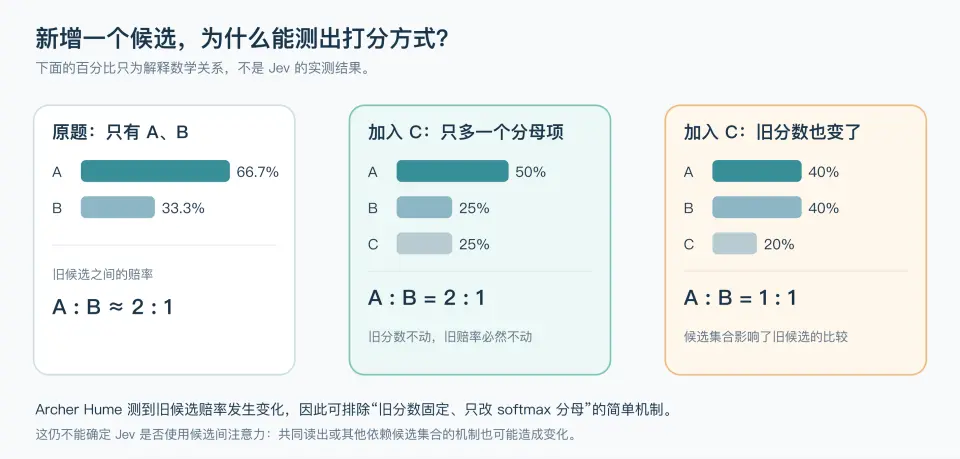
However, tester Archer Hume's tests proved that the addition of options does indeed affect the score difference of the model. He forcefully inserted the distraction "bad weather" into a set of normal options and found in ten randomly arranged tests that it indeed changed the relative odds of Finance and Technology. This directly sentenced the "black box blind review" model to death.
Since it is not a blind review, it indicates that the contestants must have "seen each other" and generated a chemical reaction before the judges gave the final scores. The open-source community provided two designs to achieve this chemical reaction.
The first design is the "Pointer Head" model designed by the Kev project. You can think of it as a "group interview." The model no longer locks contestants in a black box but lines up "Finance, Technology, Bad Weather" for the judges to see all at once.
When the judges see the contestant standing at the back, they have already formed an "overall context" about this interview in their minds. Then, standing in the last position, the judges point back to the previous contestants one by one, scoring based on their overall impression at that moment; this action is called the pointer head. When the judges look back to point and score after seeing everyone, their mindset and reference frame have already changed, and the scores given to Finance and Technology naturally fluctuate accordingly.
The second design is "Internal Discussion Among Judges," which is the "Inter-candidate Attention Module" model designed by projects like NanoJev. This time, the model is neither purely blind review nor purely group interview. It first lets "Finance" and "Technology" perform separately, condensing their performances into a long string of high-dimensional numerical comments, a term known as feature vectors.
At this point, the two comment cards are still isolated. But then a separate small model will take these two comment cards, along with the later inserted "Bad Weather" comment card, and throw them into a meeting room called the "Attention Module."
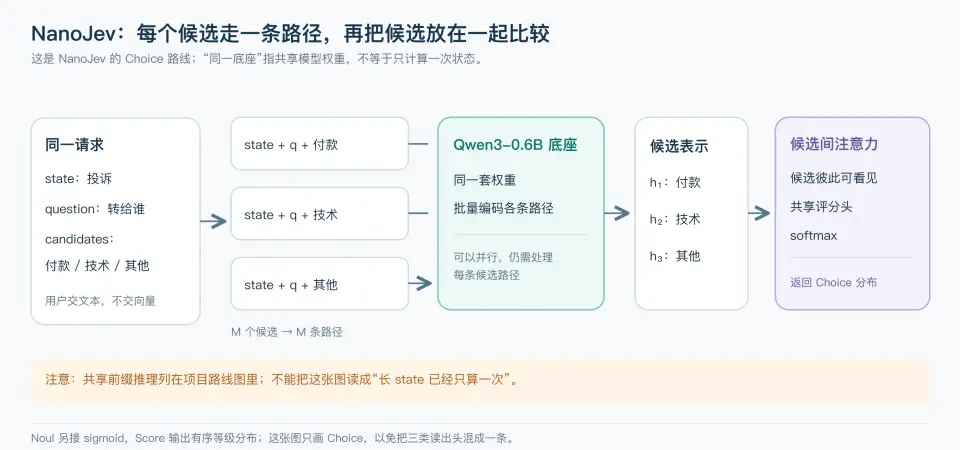
In this meeting room, these groups of numbers representing the contestants (feature vectors) will be compared and weighed against each other. Originally, Finance and Technology were difficult to distinguish, but suddenly the addition of the "Bad Weather" card disrupts and reorganizes the focus and comparative weight of the entire judges' discussion.
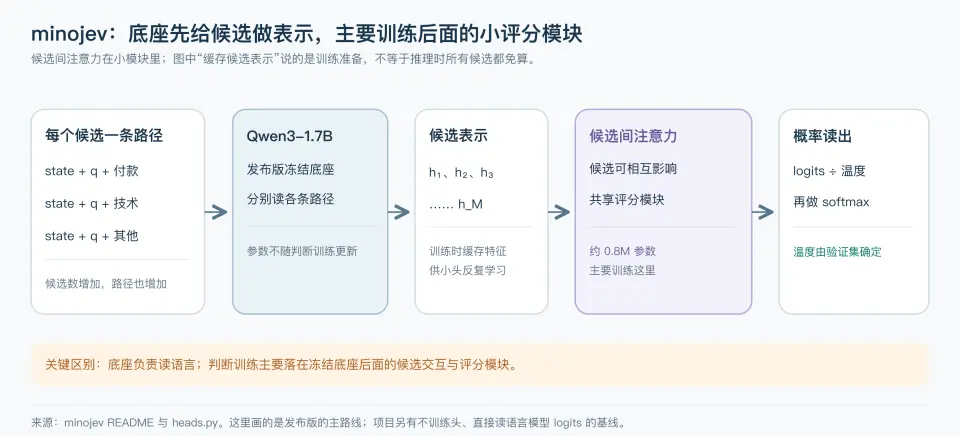
After this internal meeting of mutual undermining, the final scores given will naturally no longer reflect just the two contestants.
Why does Jev go to such lengths to ensure that these options "undermine each other" in the underlying code? This is not merely for show; it is because in real complex business scenarios, the correct answer is often not absolute but is determined by comparison. The options themselves are actually hidden clues to solving the problem.
For example, if asked where the Eiffel Tower is, the candidate options are A. Europe B. France C. Paris. When the model sees these three options simultaneously, these options themselves become hidden clues to deciphering the intent of the question. The question is not about the general location but is testing for the highest precision of geographical location.
Fourth stop: Providing Results
The final step of the process is to derive a specific score.
According to TypeSafe's official statement, Jev will directly return a probability number, never generating text word by word.
Archer Hume's external probing also confirmed this; when he increased the candidate options from two to two hundred, the response text returned by the API, although much longer, did not proportionally extend the server's processing time.
This indicates that the large model indeed skips the most time-consuming autoregressive generation step (which is predicting the next word like ChatGPT).
So, where does this final probability number actually come from? The technical implementation can vary widely, primarily depending on the methods used in the previous step of calculating options.
The approach of openjev/openjev, which does not specially handle option interactions, is to directly read the original scores (Logits) for the specified candidate letter tokens from the large model's internal vocabulary at the "answering position" where the model is supposed to generate the first word.
With the pointer head added, Kev relies on that global overview provided by the pointer head to directly output comparative scores. Meanwhile, minoev, which has a shared module, relies on that manually added shared scoring module to produce results.
Regardless of the extraction method, as long as the process is designed properly, the large model can completely abandon verbose text generation and directly extract precise mathematical probabilities at the very end of the computation, completing a system-level automatic decision.
At this point, we can clearly outline Jev's architectural model based on the evaluation and restoration.
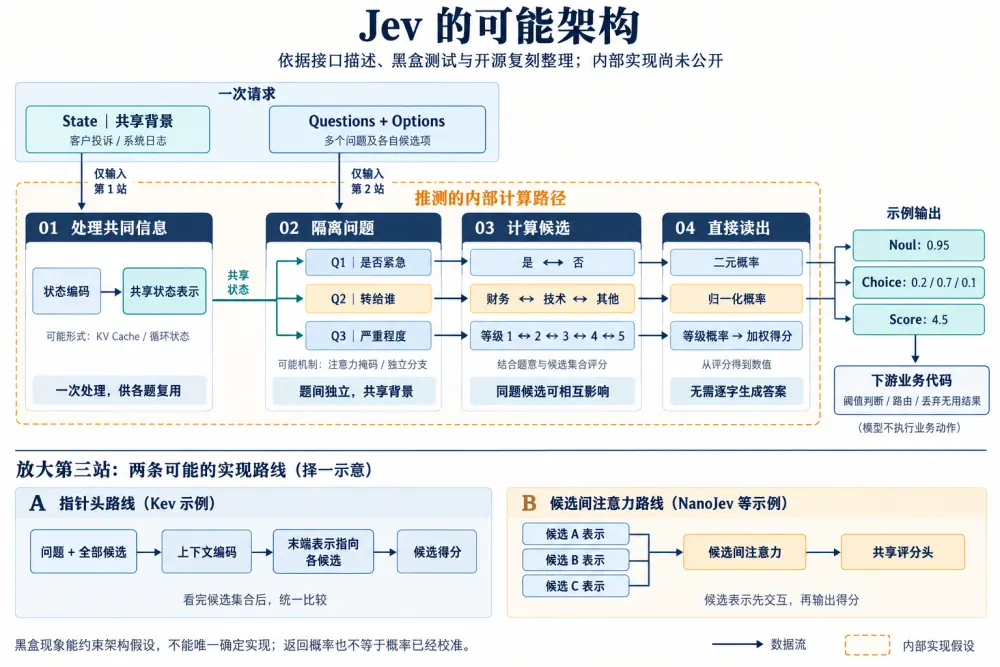
This architecture itself is not complex, and it is difficult to find any part that can be called paradigm-shifting. While it is indeed an excellent engineering optimization for specific scenarios, that is all it is.
03
The guarantee of accuracy is post-training
The architecture only guarantees speed; how is Jev's higher accuracy achieved?
It relies on what TypeSafe calls RLCD (Reinforcement Learning with Calibrated Decisions) post-training methods. Since RLCD is a non-public black box, we can only look at the potential questions and algorithm implementations from the attempts in the open-source community.
The birth of a question for RLCD training
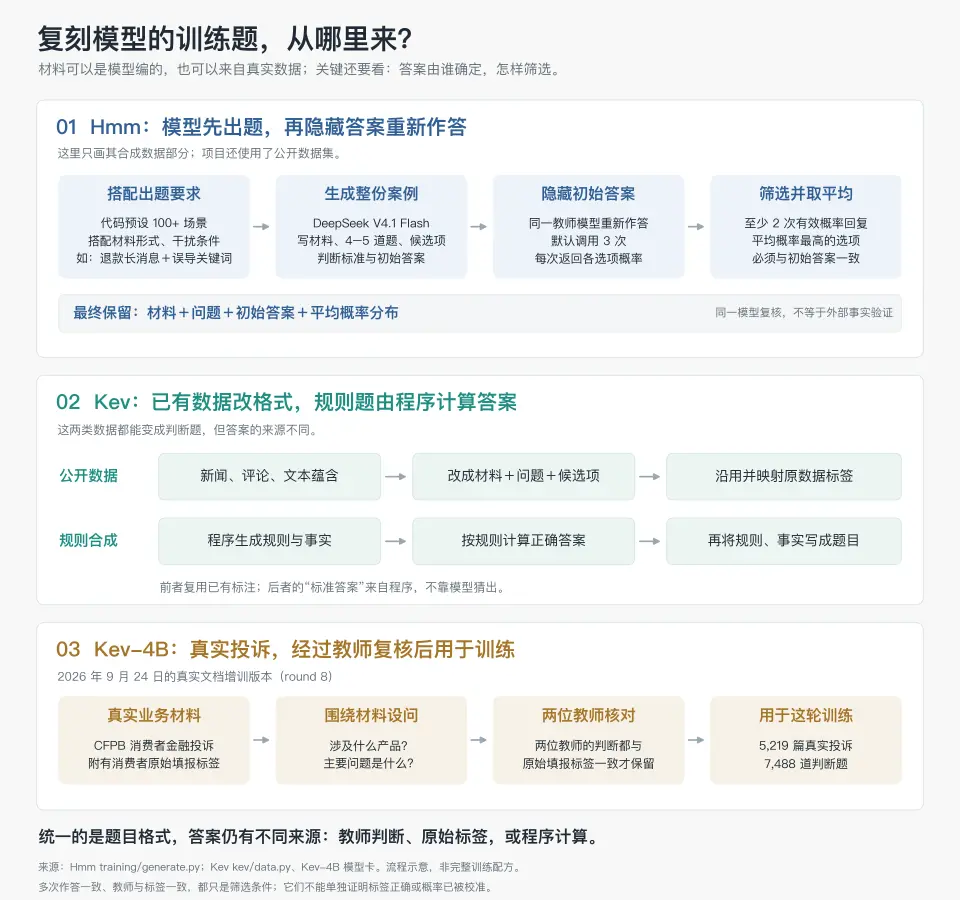
The simplest method is direct synthesis, such as the method provided by the Hmm version replica.
Researchers had DeepSeek V4.1 list over a hundred work scenarios in the code, including refund processing, fault diagnosis, relevance retrieval, email routing, etc.
Each time, they would select a scenario and pair it with material forms and question requirements. For example:
Using a long message with irrelevant details, write several refund case examples.
Add a case that is easily misled by keywords.
Attach four to five multiple-choice, true/false, or rating questions to each case.
DeepSeek V4.1 Flash then generates the entire set of materials, questions, candidate options, judgment criteria, and answers.
After that, testing whether this question can be used relies on hiding the original answers and having DeepSeek V4.1 Flash answer again, defaulting to three calls, requiring a probability for each option each time. Only questions that allow at least two valid responses can be used.
Kev's method is to unify existing datasets of news classification, comment sentiment, and text implications into a judgment format of "material + question + candidate answer" according to rules.
The model then generates rules and facts, calculates answers, and writes them down.
On September 24, Kev-4B also attempted to construct questions using real work environments. They collected 5,219 real consumer financial complaints and created questions around "what products are involved and what the main issues are." After the questions were generated, only when the judgments of two different teacher models were consistent with the original labels filled out by consumers would the labels be retained.
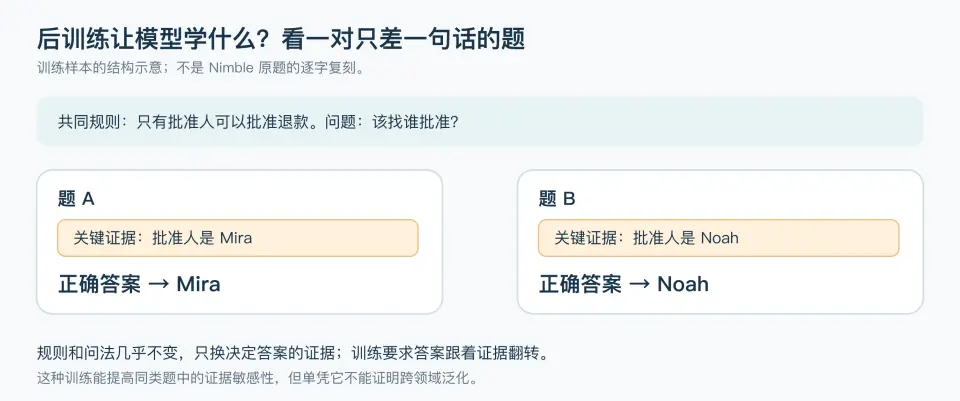
To make this training more effective, the restored test questions also specifically include some paired trap questions.
For example, the rules for two questions are exactly the same, but one key name is changed (for instance, the signer changes from the authorized Mira to the unauthorized Noah), and the answer flips directly. Such questions can effectively prevent the model from memorizing answers through Reward Hacking, forcing it to honestly learn the deep representations and connections between questions and answer options.
Is the training method of LoRA plus distillation enough?
Currently, almost all reproductions using post-training methods employ the "LoRA + teacher distillation" approach to increase the probability of correct options.
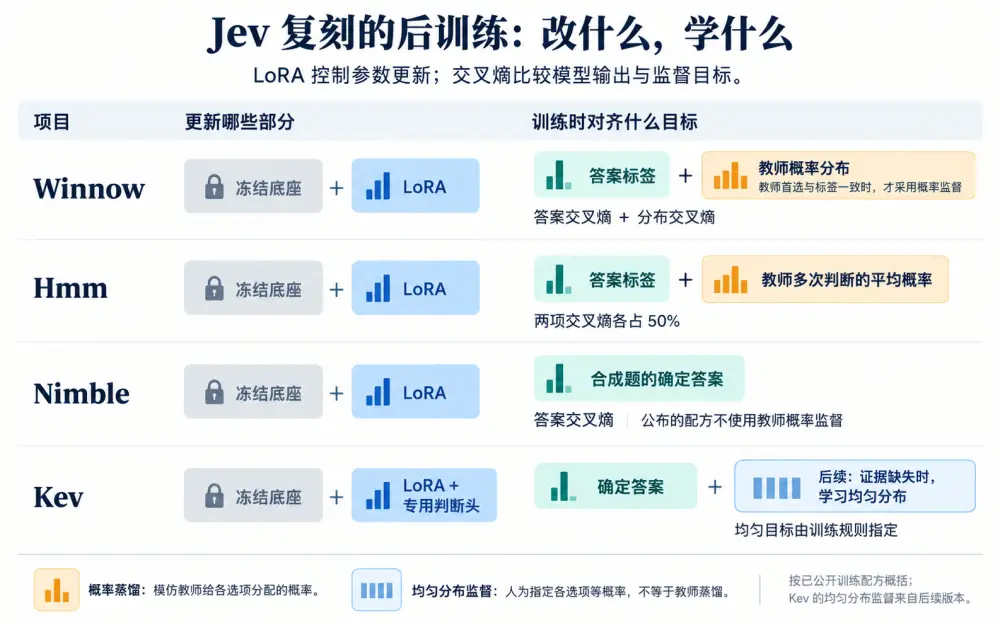
Taking Winnow as an example, it chooses to perform LoRA fine-tuning on the Gemma 4 12B instruction model. The role of LoRA is to retain the original weights of the base and train a small portion of correction parameters involved in the computation, reducing the cost of modifying the model.
Winnow simultaneously uses two types of supervision. One provides the standard answer, requiring the model to increase the probability of the correct option. The other provides the teacher's probability distribution for all options, guiding the student to approach this distribution. Winnow only adopts the second type of supervision when the first choice selected by the teacher is consistent with the standard answer.
Both are trained using cross-entropy to calculate training errors. The role of cross-entropy here is to check how much the student misallocated probabilities. The lower the probability assigned to the correct option when only the standard answer is present, the greater the penalty.
When using the teacher distribution, training will push the student to imitate the teacher's allocation for each option. For example, if the teacher allocates 80%, 15%, and 5% to A, B, and C respectively, the student will be required to learn the distinctions among these three options.
Generally speaking, LoRA, distillation, and cross-entropy are sufficient for tasks that already have prepared questions, answers, and reference distributions (such as this probability prediction task) because they are only learning a probability.
However, distillation actually learns the teacher's probability, not the real probability as mentioned by RCLD. How to bridge the gap of distillation through the ratio of facts/teachers is currently unclear in reproductions.
Theoretically, to achieve Jev's claims, it can only rely on larger data volumes and more sample-efficient learning methods.
Of course, if such a small judgment model can achieve the judgment accuracy of a large model, then it is still very useful even if it hasn't solved this.
Calibration may still be the secret weapon.
In addition, Jev has another secret weapon, which is its claimed calibration ability.
The number of questions a model answers correctly and whether it accurately expresses its confidence are two different things. A model might only answer 70% correctly but report a confidence of 90%.
To verify whether Jev is blindly confident, Archer Hume conducted a "lie detection experiment."
He first fed Jev 1,200 MMLU (Massive Multitask Language Understanding) test questions, then divided all selected answers into ten levels based on the probabilities reported by the system. After complex weighted calculations, Jev's calibration error was only 0.031.
In 30 simple three-digit multiplication questions, Jev answered 86.7% correctly, while its reported average confidence was 83%, which was very consistent. When the questions changed to more difficult "two-step application problems," its accuracy plummeted to 32%, the key point is that its reported average confidence also obediently dropped to 30%.
In this regard, post-training can generally improve probability performance, but often leads to models becoming more blindly confident.
To restore Jev's relatively accurate calibration ability, the replica version used some methods. For example, Kev explicitly requires the model to reduce certainty in the absence of evidence. It adds samples where key evidence is removed in the training set and lowers their probabilities in the answers, so the model is penalized for concentrating probabilities on a certain option without basis.
However, more reproductions only perform a kind of superficial temperature calibration.
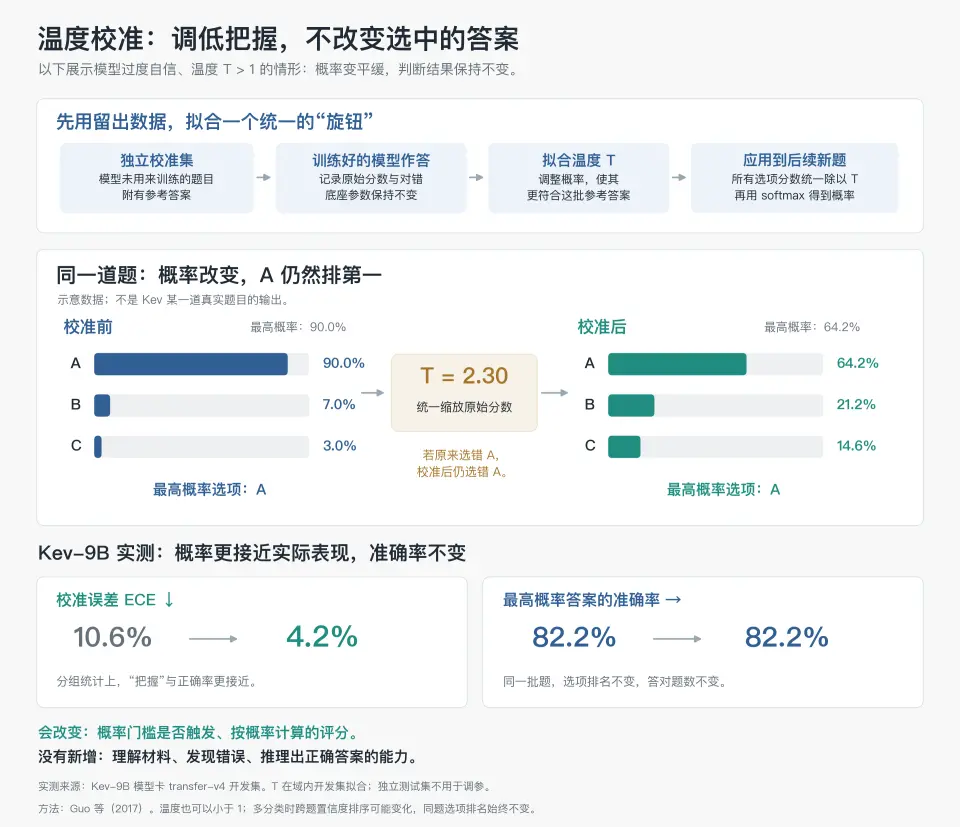
Engineers will present a small batch of test questions that the trained model has not seen. If they find the model is overly confident, the system will calculate how much the overall confidence should be adjusted based on this batch of questions.
Once the knob is adjusted, the model will be forced to wear a humility filter when outputting probabilities in the future, resulting in a more moderated probability.
This will not change the ranking of options for the same question, so the highest probability answer remains unchanged. However, the probability threshold and scoring based on probabilities may change.
This method is still quite effective. For example, after temperature calibration, the calibration error of Kev-9B dropped from about 10.6 percentage points to 4.2 percentage points, while the number of correctly answered questions remained unchanged.
Saying it is a superficial fix is because this actually comes from lowering overall confidence, rather than from more accurately distinguishing whether it should be confident.
If Jev has indeed achieved an effective improvement in calibration rate, then they might have some real skills here.
04
What is the extent of Jev's applicable boundaries?
There is no doubt that Jev has practical application significance. It restores tasks that originally only required quick decision-making back to quick decision-making itself.
In the entire process of the Agent, there are many explicit requirements for request classification and routing, retrieval result sorting, and detailed checks. These are all areas where Jev can play a role.
For example, customer service routing, product categorization, feedback analysis, and data labeling are all common high-frequency scenarios in our daily tasks.
But how large its applicable boundaries are determines whether it has the paradigm value it claims.
From the current benchmarks, it does indeed have a certain degree of generality. The Nimble team tested fact-checking, intent routing, semantic entailment, content review, medical Q&A, and other tasks using 13 groups of a total of 3,880 public data, with Jev achieving an average accuracy of 76.0% across datasets.
This indicates that Jev can indeed handle various judgment tasks.
However, true generality has two hurdles.
The first is difficult tasks; if it can only perform simple judgments, its applicable range is very limited.
First, we need to define what constitutes difficulty in judgment. Generally, we believe that the more steps, conditions, and detailed understanding required, the more difficult the question is.
Identifying "the user wants a refund" only requires understanding the literal meaning, but judging "should this refund be approved" requires checking dates, calculating deadlines, and comparing the priority of terms, which is clearly more difficult. If a judgment requires three steps of reasoning to reach a conclusion, then the third step depends on the result of the second step, which is a multi-step dependency. If the policy is misidentified in the first step, even if the subsequent calculations are completely correct, the final judgment will still be wrong.
In the difficult question test of JevBench, JevBench set some factors related to the difficulty of judgment questions, including multi-condition judgments, continuous evidence searches, and comparisons of dates and numbers among three options. In this batch of questions, Jev's multi-step search accuracy was 85.7%, long policy judgment was 60.5%, and time and number judgment was only 26.7%, all far inferior to Flash-level models. In total, Jev answered 74.1% of the difficult questions correctly, while DeepSeek V4.1 Flash scored 95.0%, roughly on par with human experts.
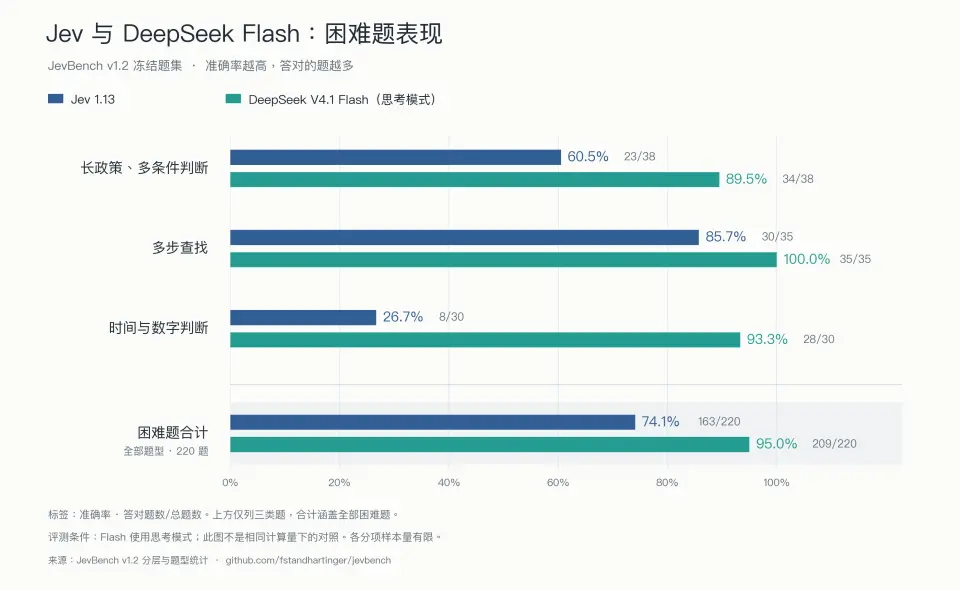
Although the median time spent on corresponding test requests was about 0.67 seconds and 3.15 seconds, Jev's speed was nearly four times faster. However, such a large accuracy gap makes the choice of what to do in some complex judgment tasks (such as stock trading, which everyone hopes for) almost self-evident.
Moreover, the multi-step search accuracy mentioned here is not multi-step reasoning; it mainly involves searching. In Archer Hume's tests, Jev achieved an accuracy of 86.7% in simple multiplication, but when it came to two-step application problems, the accuracy dropped to 32%.
Briantrust conducted a more detailed evaluation, which also highlighted Jev's shortcomings on difficult questions. It compared Jev with the GPT 5.6 Luna model, asking the models to choose the correct one from two candidate answers, ultimately comparing 616 valid question pairs. The knowledge question gap between the two models was only 1.6 percentage points, while the gap in math and reasoning expanded to 19.3 percentage points, and in coding, it reached 20 percentage points.
Therefore, regarding the hurdle of difficult judgments, Jev can hardly claim to have overcome it.
The other hurdle is generalization.
If Jev can truly generalize, it should be able to achieve better generalization, improving the accuracy of judgments on other questions based on what it has learned.
Otherwise, it is just a "specialized judgment model" with a slightly broader applicable range, not significantly different from previous judgment models.
Existing multiple direct testing evidence can prove that Jev indeed possesses a certain degree of generalization ability, but this ability is extremely unstable within the domain. Once it steps out of familiar scenarios, its performance still faces significant risks.
First, under completely identical tasks and facts, Jev's judgments are easily influenced by the way information is presented. In the OpenProse experiment, without changing any facts, questions, or computational loads, when key relationships were concentrated at the front of the text, Jev's accuracy was 80.5%, but when these relationships were moved to the middle, the accuracy plummeted to 40.9%.
This indicates that even without changing business domains, Jev's robustness in representation is severely lacking. Its judgment ability highly depends on how external programs feed it data.
Secondly, when faced with new questions under the same evaluation system, Jev's performance fluctuations are also quite evident. In the new version v1.4 of JevBench, which added 308 closed difficult questions, Jev's accuracy dropped from 86.6% on public questions to 36.7%. In contrast, the DeepSeek V4.1 Flash using a thinking mode maintained an accuracy of 94.8%.
The high scores Jev previously achieved on public questions cannot automatically carry over to unknown complex tests.
When testing further pushes towards real business migration, Jev's performance is similarly mixed. A positive example comes from the prompt injection detection of Agent Journal, where Jev achieved an accuracy of 83.65% on the original test set, and when directly migrated to another test set containing over two thousand external data points, the accuracy even improved to 95.58%, far exceeding traditional baseline models.
This indicates that it can indeed adapt to changes in data sources for certain specific tasks.
However, in more complex business logic, this generalization often fails. Scarif Labs used it to determine whether software updates were safe. When moving the model from one software ecosystem to another, Jev's ability to distinguish between safe and dangerous updates (AUROC) dropped from 0.851 to 0.605 (close to the random guessing rate of 0.5).
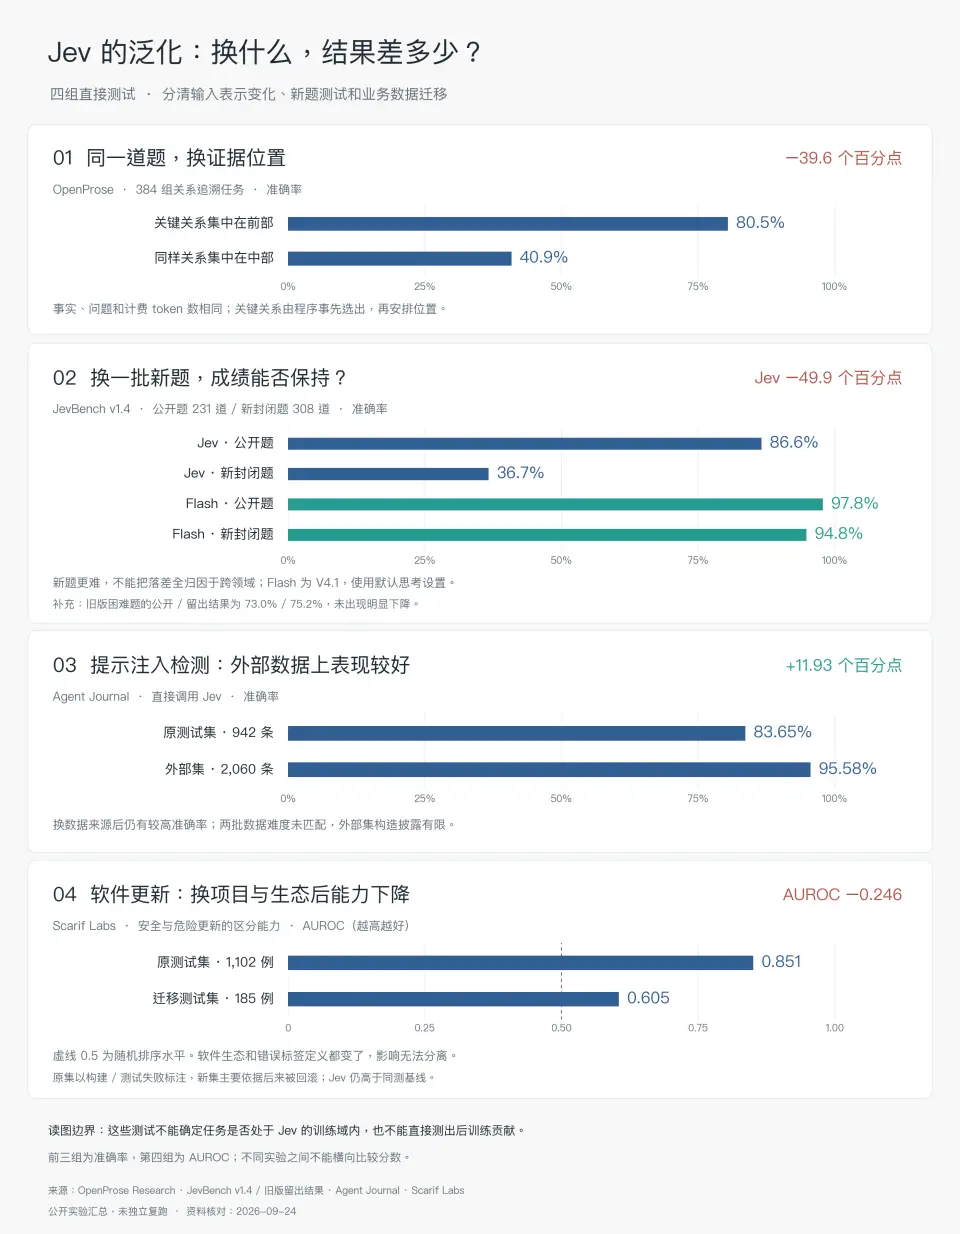
Therefore, we can at least say that Jev's generalization is currently quite limited and questionable. It is still far from the standard of universal generalization.
Since Jev has not overcome these two hurdles of universality, where should we use it now?
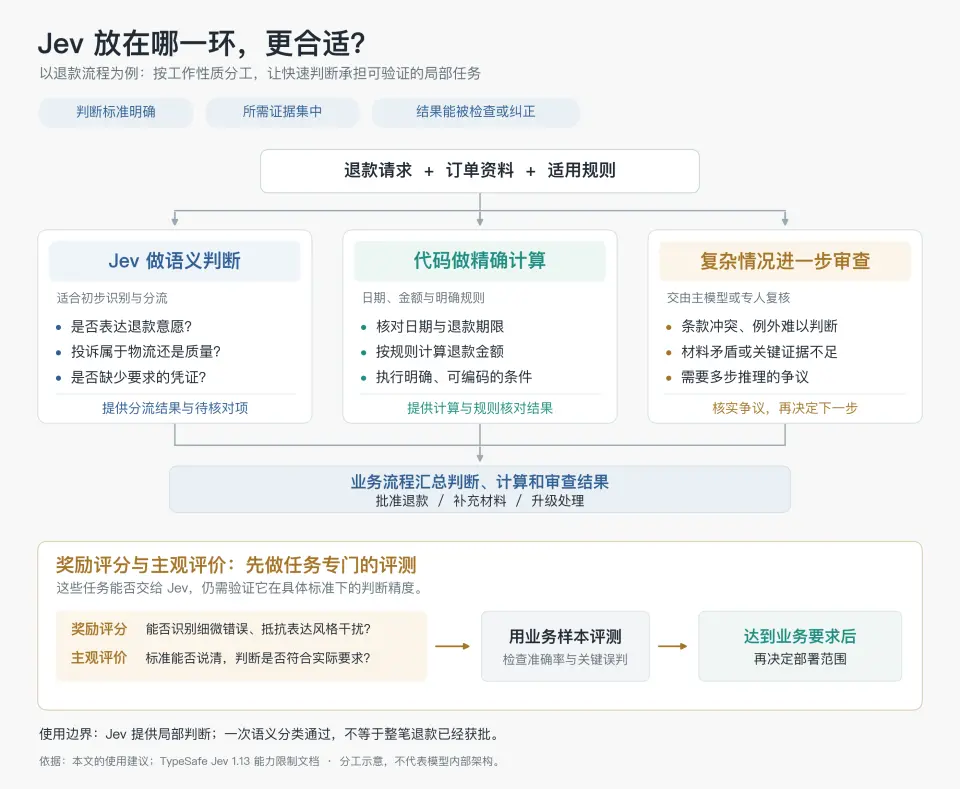
A more appropriate positioning is to place Jev in scenarios where the standards are clear, evidence is concentrated, and the judgment results can be checked or corrected.
Taking refunds as an example. Determining whether a user has expressed a desire for a refund, whether the complaint involves logistics or product quality, and whether additional proof is needed are all semantic judgments that can be verified individually. These questions arise frequently, usually do not require generating an explanation, and do not need the main model to engage in reasoning every time. Jev can take on preliminary screening here.
However, approving a refund changes the situation. Whether it exceeds the deadline requires code to verify dates, refund amounts need to be calculated according to rules, and in cases of conflicting terms or exceptions, further review is necessary. TypeSafe itself also recommends delegating mathematical operations and date comparisons to code, and minimizing multi-layer dependencies in judgments.
This division of labor allows its speed to be utilized in the right places.
As for uses that rely more on precision, such as reward models, the judgments often involve those superficially reasonable yet actually incorrect answers. The model also needs to discern subtle differences and resist interference from expression styles.
For tasks where the rules are difficult to define, such as those involving more subjective evaluations, it is advisable to first test Jev's accuracy before deployment.
At this point, Jev can serve as a candidate solution, but users still need task-specific evaluations.
Additionally, there is one account that cannot be overlooked. Jev's own responsiveness does not mean that the entire Agent becomes faster after adding it.
If it can process a batch of simple requests in advance, preventing these requests from calling the main model, then the speed and cost advantages have a chance to materialize.
However, if Jev is called first every time and then the same main model is still called, the additional judgments must save enough subsequent work to offset its own time and costs.
In a set of Agent memory retrieval experiments on GitHub, the system introduced Jev to determine whether the retrieved information was useful. To avoid Jev mistakenly discarding useful information, developers had to repeatedly adjust the judgment criteria.
Although they ultimately allowed all 20 conventional cases to pass, the cost was clear: the system's total latency increased from 649 milliseconds to 1087 milliseconds, and the cost per thousand calls more than doubled.
If the main model itself has the ability to filter answers from complex materials, adding Jev as a judgment layer not only adds waiting time but also carries the risk of missing key evidence due to misjudgment.
05
How true is Jev's disruptiveness?
In the end, the core question Jev leaves us with is, what exactly is it learning?
Logically, a model used for judgment learns representations that enable it to make effective judgments based on new facts.
This is one of the most challenging representations.
Universal judgment requires the simultaneous invocation of multiple capabilities; it cannot be assumed to be easier than generating answers just because it outputs a single probability.
Take refunds as an example. Seeing "I want a refund" relies primarily on language understanding to identify the desire for a refund. But asking "According to this policy, should the refund be approved?" requires the model to understand the policy, match facts like purchase date and product condition to specific terms, and then handle exceptions.
This is essentially the foundational capability of the language model behind Jev.
The final question, "Does the refund help retain this customer?" requires predicting behavioral outcomes. This is the part that the model needs to be trained on.
It needs to learn which facts influence outcomes, under what conditions they influence, and whether these relationships still hold in different scenarios.
All three questions can output "the probability of yes," but the knowledge and calculations required behind them differ.
To bridge the gap from "predicting how others will judge" to "reliably predicting the consequences of actions," how much data and training do we really need?
At least for humans, comprehensive decision-making is one of the hardest things to learn. It is as complex as the taste and comprehensive utilitarian calculations mentioned in our previous articles.
Therefore, I am very skeptical that the learning methods revealed in this article can support such complex representations.
Of course, we can view Jev as a highly ingenious engineering tool.
In business pipelines with clear rules and complete materials, it can significantly reduce waiting time and computational costs, and its value is undeniable.
However, before proving that it has indeed learned some universal judgment principles, it is premature to crown it with the title of "paradigm innovation."
 Risk warning